CourtMesh
Search 315M+ Indian court cases from the Supreme Court, High Courts and District Courts. REST API with official Python, Node and MCP SDKs.
About CourtMesh
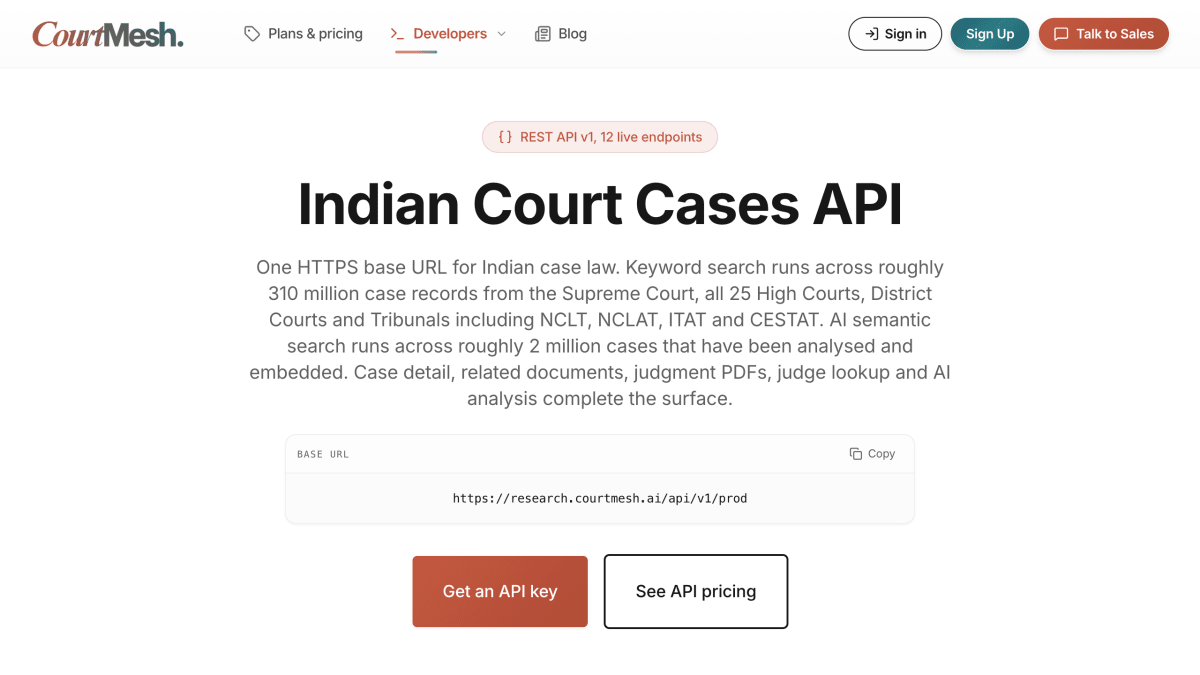
CourtMesh's Indian Court Cases API provides REST access to Indian case law through a single HTTPS base URL. Keyword search covers roughly 310 million case records drawn from official court portals, spanning the Supreme Court of India, all 25 High Courts, District Courts, and tribunals including NCLT, NCLAT, ITAT and CESTAT, accessible through a search endpoint. A separate, smaller vector index of roughly 2 million cases that have undergone AI analysis and embedding supports semantic search through its own endpoint. The API exposes 12 live endpoints covering case detail, related documents, judgment PDFs, judge lookup, and AI analysis, with the non-embedded endpoints reaching the full record set regardless of embedding status.
Authentication uses an API key sent via an X-API-Key header or an Authorization Bearer token, with GET /health as the only unauthenticated endpoint. Deactivated keys or suspended accounts/organizations are rejected on each request rather than at cache expiry. Rate limits are ten requests per minute per key on a rolling sixty-second window, with limit information returned in response headers and a 429 response with retry timing when exceeded; rejected requests still count against the limit.
API access is tied to account plan: at the time of writing it is enabled on Enterprise accounts, with a self-serve developer tier described as rolling out. Accounts without API entitlement receive an HTTP 403 response on their first call. Details on request volumes, plans, and per-endpoint pricing are covered on a separate pricing page.
Key features
- AI semantic search across roughly 2 million analysed and embedded cases
- 12 live REST endpoints for case detail, related documents, judgment PDFs, judge lookup and AI analysis
- Judge lookup via a dedicated search endpoint
- Authentication via X-API-Key header or Authorization Bearer token
- Rate limit headers and cursor-based pagination for bulk extraction
Frequently asked questions
What data does the API cover?
The keyword index holds roughly 310 million case records from the Supreme Court, all 25 High Courts, District Courts and tribunals including NCLT, NCLAT, ITAT and CESTAT. A separate, smaller vector index of about 2 million cases supports AI semantic search.
How is the API authenticated and rate limited?
Requests use an X-API-Key header or an Authorization: Bearer token, and only GET /health is unauthenticated. Each key is limited to ten requests per minute on a rolling sixty second window, enforced with X-RateLimit response headers.
Is there a free tier?
The page mentions a free trial and states that a self-serve developer ladder is rolling out, but at the time of writing API access is enabled on Enterprise accounts.
How do I get started?
Sign up, generate an API key from the API Keys screen at research.courtmesh.ai/api-keys, and call the single base URL https://research.courtmesh.ai/api/v1/prod with curl or any HTTP client, no SDK required.
What happens if I exceed the rate limit or lack API access?
Exceeding the ten-per-minute limit returns HTTP 429 with a retryAfter value, while an account not entitled to API access gets HTTP 403 on the first call.

SerpApi - Search API
SerpApi's Search API makes it easy and fast to scrape Google and other search engines.
Show your product to thousands of developers
· 100k monthly pageviews
· 7k newsletter subscribers
You might also like
Code.gov
GovernmentThe primary platform for Open Source and code sharing for the U.S. Federal Government.
Colorado Information Marketplace
GovernmentColorado State Government Open Data.
Conversor IAE CNAE
GovernmentSpanish IAE/CNAE tax activity codes, 2009→2025 crosswalk and AEAT obligations.
Data.gov
GovernmentUS Government Data.
Data.parliament.uk
GovernmentContains live datasets including information about petitions, bills, MP votes, attendance and more.
Data USA
GovernmentUS Public Data.